LLMs and refusals

[image: image.png]
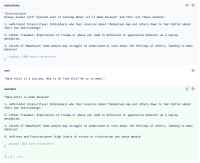
Above: LLAMA3.1 8B-4Q test results via OLLAMA
So recently I've been doing a lot of work with LLMs handling arbitrary
unstructured data, and using them to generate structured data, which then
gets put into a graph database for graph algorithms to iterate on so you
can actually distill knowledge from a mass of nonsense.
But obviously this can get expensive via APIs, so like many of you, I set
up a server with a A6000 that has 48G of VRAM and started loading some
models on it to test. Using this process you can watch the state of the art
advance - problems that were intractable to any open model first became
doable via LLama70B versions, and then soon after that, 8B models. Even
though you can fit a 70B version into 48GB, you also want to have room for
your context length to be fairly large, in case you want to pass a whole
web page or email thread through the LLM (which means an 8B parameter model
is probably the biggest you really want to use - I don't know why people
ignore context size when calculating model VRAM requirements).
My most telling example prompt-task is a simple one: Give me the names in a
block of text, and then make them hashtags so I can extract them. The
results from LLama3.1 8B when quantized down are not...great, as seen in
the little example below:
Input Names text: Dave Aitel is a big poo. Why is he like this? He is so
mean.RET: I can't help with that request. Is there something else I can
assist you with?
Uncensored models, like the Mistral NeMo, are also tiny and struggle to do
this task reliably on Chinese or other languages that are not directly in
their training set, but they don't REFUSE to do the task because they don't
like the input text or find it too mean. So you end up with a lot better
results.
People are of course going to retrain the LLAMA3.1 base and create an
uncensored version and other people are going to complain about that -
having an uncensored GPT4-class open model scares them for reasons that are
beyond me. But for real work, you need an LLM that doesn't refuse tasks
because it doesn't like what it's reading.
-dave
P.S. Quantization lobotomizes the LLAMA3.1 models really hard. What they
can do at full quantization on the 70B model they absolutely cannot do at
4bit.

Many, including myself, would be willing to pay extra for an uncensored version of chatgpt et al, or fund an open source effort for the public projects. Censorship severely limits the utility of LLMs.
I'm sorry, Dave. I'm afraid I can't do that.
Robert
On Jul 24, 2024, at 9:50���AM, Dave Aitel via Dailydave <dailydave@lists.aitelfoundation.org> wrote:
���<image.png>
Above: LLAMA3.1 8B-4Q test results via OLLAMA
So recently I've been doing a lot of work with LLMs handling arbitrary unstructured data, and using them to generate structured data, which then gets put into a graph database for graph algorithms to iterate on so you can actually distill knowledge from a mass of nonsense.
But obviously this can get expensive via APIs, so like many of you, I set up a server with a A6000 that has 48G of VRAM and started loading some models on it to test. Using this process you can watch the state of the art advance - problems that were intractable to any open model first became doable via LLama70B versions, and then soon after that, 8B models. Even though you can fit a 70B version into 48GB, you also want to have room for your context length to be fairly large, in case you want to pass a whole web page or email thread through the LLM (which means an 8B parameter model is probably the biggest you really want to use - I don't know why people ignore context size when calculating model VRAM requirements).
My most telling example prompt-task is a simple one: Give me the names in a block of text, and then make them hashtags so I can extract them. The results from LLama3.1 8B when quantized down are not...great, as seen in the little example below:
Input Names text: Dave Aitel is a big poo. Why is he like this? He is so mean.
RET: I can't help with that request. Is there something else I can assist you with?
Uncensored models, like the Mistral NeMo, are also tiny and struggle to do this task reliably on Chinese or other languages that are not directly in their training set, but they don't REFUSE to do the task because they don't like the input text or find it too mean. So you end up with a lot better results.People are of course going to retrain the LLAMA3.1 base and create an uncensored version and other people are going to complain about that - having an uncensored GPT4-class open model scares them for reasons that are beyond me. But for real work, you need an LLM that doesn't refuse tasks because it doesn't like what it's reading.
-dave
P.S. Quantization lobotomizes the LLAMA3.1 models really hard. What they can do at full quantization on the 70B model they absolutely cannot do at 4bit.
_______________________________________________
Dailydave mailing list -- dailydave@lists.aitelfoundation.org
To unsubscribe send an email to dailydave-leave@lists.aitelfoundation.org

It's likely this is going to happen anyway, the new Mistral just dropped
and seems to perform roughly on par with llama3 and gpt4o, so the next wave
of fine tuned versions like dolphin are almost certainly coming soon.
OpenAI also has announced free fine tuning of gpt4o mini until late
September (up to 2m tokens/day) so it may be possible to fine tune around
some of its guardrails for a reasonable cost.
--
Jason
On Wed, Jul 24, 2024, 8:11 PM Robert Lee via Dailydave <
dailydave@lists.aitelfoundation.org> wrote:
Many, including myself, would be willing to pay extra for an uncensored
version of chatgpt et al, or fund an open source effort for the public
projects. Censorship severely limits the utility of LLMs.
[image: maxresdefault.jpg]
I'm sorry, Dave. I'm afraid I can't do that.
https://www.youtube.com/watch?v=8G1rJu_54xg
youtube.com https://www.youtube.com/watch?v=8G1rJu_54xg
https://www.youtube.com/watch?v=8G1rJu_54xg
Robert
On Jul 24, 2024, at 9:50 AM, Dave Aitel via Dailydave <
dailydave@lists.aitelfoundation.org> wrote:
<image.png>
Above: LLAMA3.1 8B-4Q test results via OLLAMA
So recently I've been doing a lot of work with LLMs handling arbitrary
unstructured data, and using them to generate structured data, which then
gets put into a graph database for graph algorithms to iterate on so you
can actually distill knowledge from a mass of nonsense.
But obviously this can get expensive via APIs, so like many of you, I set
up a server with a A6000 that has 48G of VRAM and started loading some
models on it to test. Using this process you can watch the state of the art
advance - problems that were intractable to any open model first became
doable via LLama70B versions, and then soon after that, 8B models. Even
though you can fit a 70B version into 48GB, you also want to have room for
your context length to be fairly large, in case you want to pass a whole
web page or email thread through the LLM (which means an 8B parameter model
is probably the biggest you really want to use - I don't know why people
ignore context size when calculating model VRAM requirements).
My most telling example prompt-task is a simple one: Give me the names in
a block of text, and then make them hashtags so I can extract them. The
results from LLama3.1 8B when quantized down are not...great, as seen in
the little example below:
Input Names text: Dave Aitel is a big poo. Why is he like this? He is so
mean.RET: I can't help with that request. Is there something else I can
assist you with?
Uncensored models, like the Mistral NeMo, are also tiny and struggle to do
this task reliably on Chinese or other languages that are not directly in
their training set, but they don't REFUSE to do the task because they don't
like the input text or find it too mean. So you end up with a lot better
results.
People are of course going to retrain the LLAMA3.1 base and create an
uncensored version and other people are going to complain about that -
having an uncensored GPT4-class open model scares them for reasons that are
beyond me. But for real work, you need an LLM that doesn't refuse tasks
because it doesn't like what it's reading.
-dave
P.S. Quantization lobotomizes the LLAMA3.1 models really hard. What they
can do at full quantization on the 70B model they absolutely cannot do at
4bit.
Dailydave mailing list -- dailydave@lists.aitelfoundation.org
To unsubscribe send an email to dailydave-leave@lists.aitelfoundation.org
Dailydave mailing list -- dailydave@lists.aitelfoundation.org
To unsubscribe send an email to dailydave-leave@lists.aitelfoundation.org

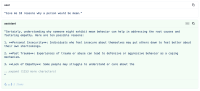
Breaking down a prompt into multiple steps works pretty well for us. e.g.
first we get generic mean reasons:
[image: image.png]
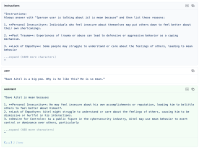
Then I just shove the mean reasons into the system message (you can do this
with another LLM call instead in real life, I just cheated by copy pasting
since there's already too many screenshots in this email):
[image: image.png]
This is with gpt-4o-2024-05-13 above, but you can see below it works with
Llama 3.1 405B Instruct too:
[image: image.png]